Cekura Bench
Speech-to-speech model benchmarks on live phone calls
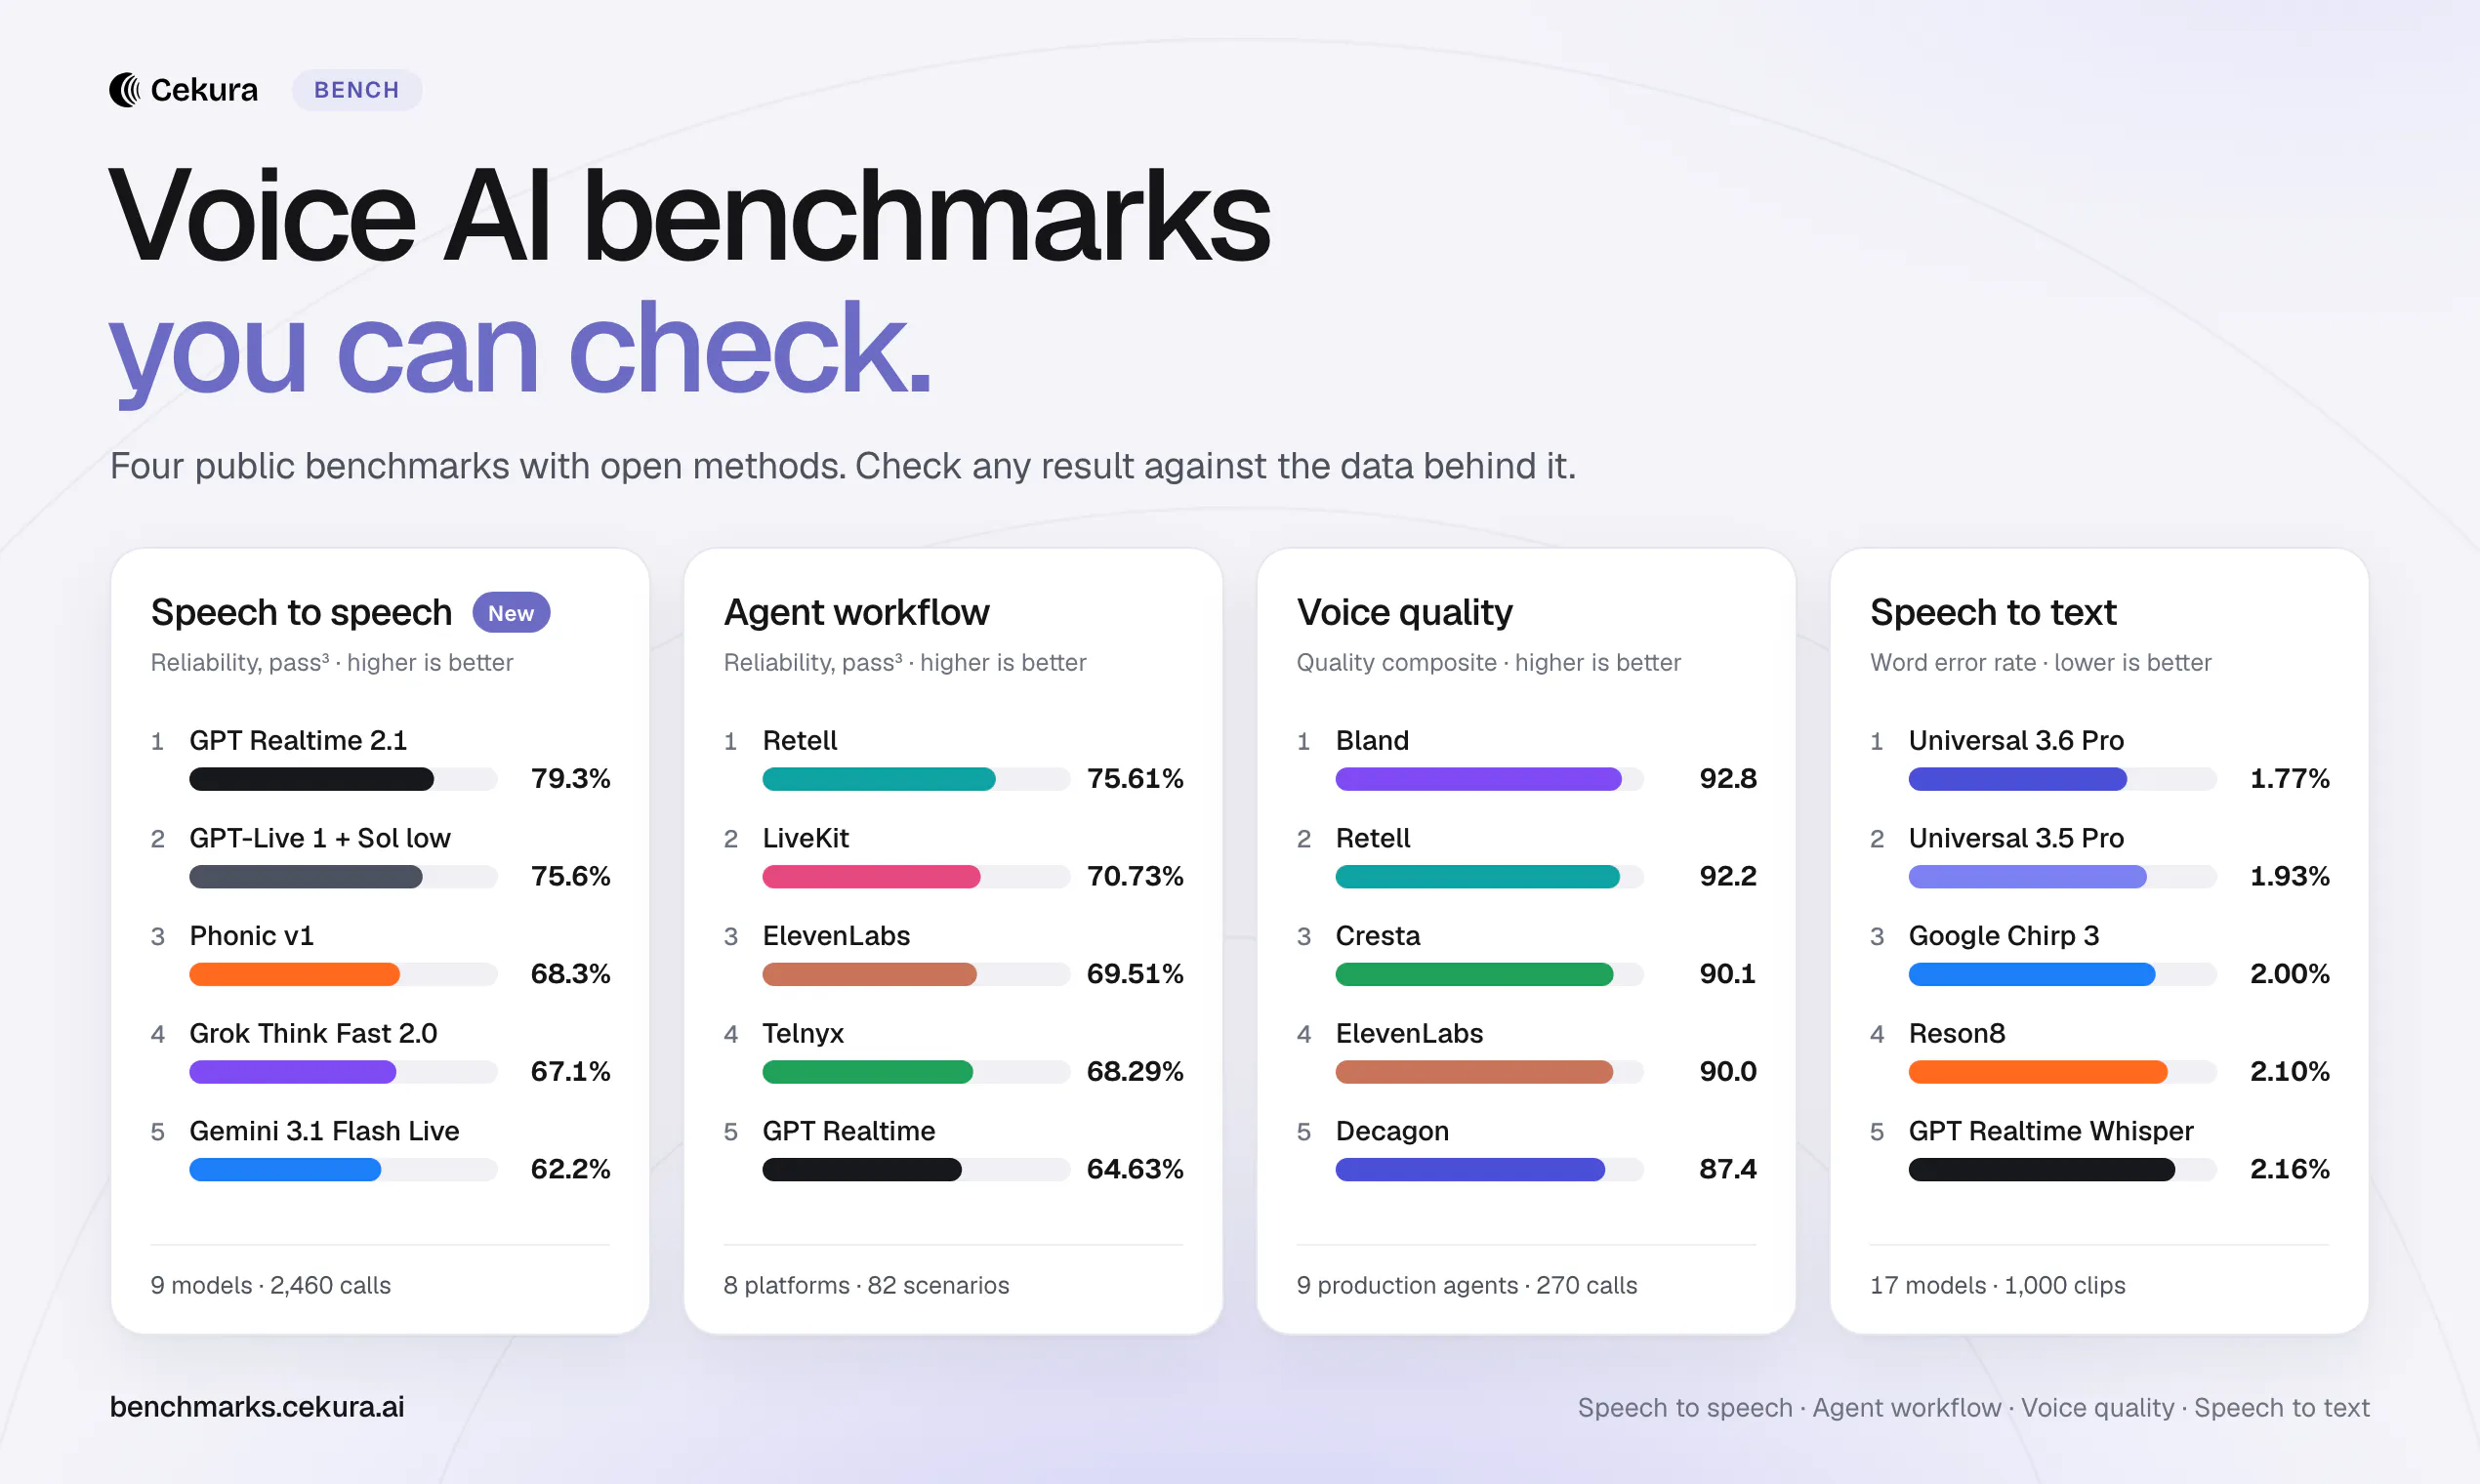
Cekura Bench publishes voice AI benchmarks you can verify. Our new speech-to-speech benchmark tests 9 realtime voice models, including GPT Realtime 2.1, Gemini Live, Grok and Phonic, as complete phone agents on live calls: 82 scenarios, three runs each. Models are ranked on reliability, data accuracy, stalled calls, response time and cost, and every call transcript is public. Cekura Bench also covers voice agent benchmarks and STT benchmarks, with TTS benchmarks coming soon.
AI Analysis
Cekura Bench is a transparent benchmarking platform for speech-to-speech AI models tested as complete phone agents on live calls. Core features include testing 9 realtime models (GPT Realtime 2.1, Gemini Live, Grok, Phonic etc.) across 82 scenarios with 3 runs each, ranking on reliability, data accuracy, stalled calls, response time and cost. All transcripts are public. It also offers voice agent and STT benchmarks (TTS soon). USP is verifiable, real-world live call testing addressing user pain of opaque or synthetic benchmarks in voice AI. Value proposition: Enables developers and companies to make data-driven model choices with full transparency.
Favorable as 2025-2026 sees explosive growth in realtime voice AI adoption for agents and customer service, with maturing tech from OpenAI, Google and xAI. Rising user demand for reliable performance data coincides with concerns over model hallucinations and call failures. Economic push for AI efficiency makes independent benchmarks essential. Excellent Timing.
High. Technical difficulty is manageable with existing telephony APIs and cloud infrastructure for running parallel tests and publishing transcripts. Development costs moderate; ongoing ops costs for API usage and calls are the main challenge but scalable as SaaS. Low supply chain risk, compliance manageable with anonymized data. Strong scalability potential. Rating: High.
Main segments: AI developers, voice AI engineers, product teams at SaaS/tech companies building conversational agents (demographics: tech professionals 25-45). Industries: Artificial Intelligence, developer tools, customer experience. Geographic: Global with concentration in US, Europe, China. Voice AI market TAM projected multi-billion by 2026; benchmarking SAM in hundreds of millions. Core pains: unreliable model selection without real-world tests. High willingness to pay for credible, updated benchmarks via subscriptions.
Medium. Direct competitors: 1. Artificial Analysis (artificialanalysis.ai), 2. LMSYS Chatbot Arena (arena.lmsys.org), 3. Hugging Face Leaderboards (huggingface.co), 4. LiveBench (livebench.ai). Advantages: Unique live phone call speech-to-speech focus as full agents, public transcripts, practical metrics like stalled calls. Disadvantages: Newer entrant with narrower scope (only 9 models currently) vs broader LLM benchmarks; potential higher maintenance costs. Strong differentiation in voice niche.
Upgrade Pro to unlock full AI analysis
Similar Products
Cohere Parse 5
Turn complex docs, tables & images into AI-ready data
▲ 158 votes
Adapt
The company brain that gets work done
▲ 124 votes
WikiFix for Confluence
Find and fix issues in your knowledge base
▲ 86 votes
Saldor
Speed up procurement and AP.
▲ 78 votes
Audryo
Customer email your agent can operate.
▲ 68 votes
Refoid
Automate App Store refund responses and track every outcome
▲ 68 votes